Key Takeaways
- Match the search API to the agent’s specific needs.
- Compare relevance, freshness, speed, reliability, and cost.
- Test providers using realistic queries and workflows.
- Review source quality and citation accuracy.
- Consider security, scalability, and total operating costs.
- Run a small pilot before making a final choice.
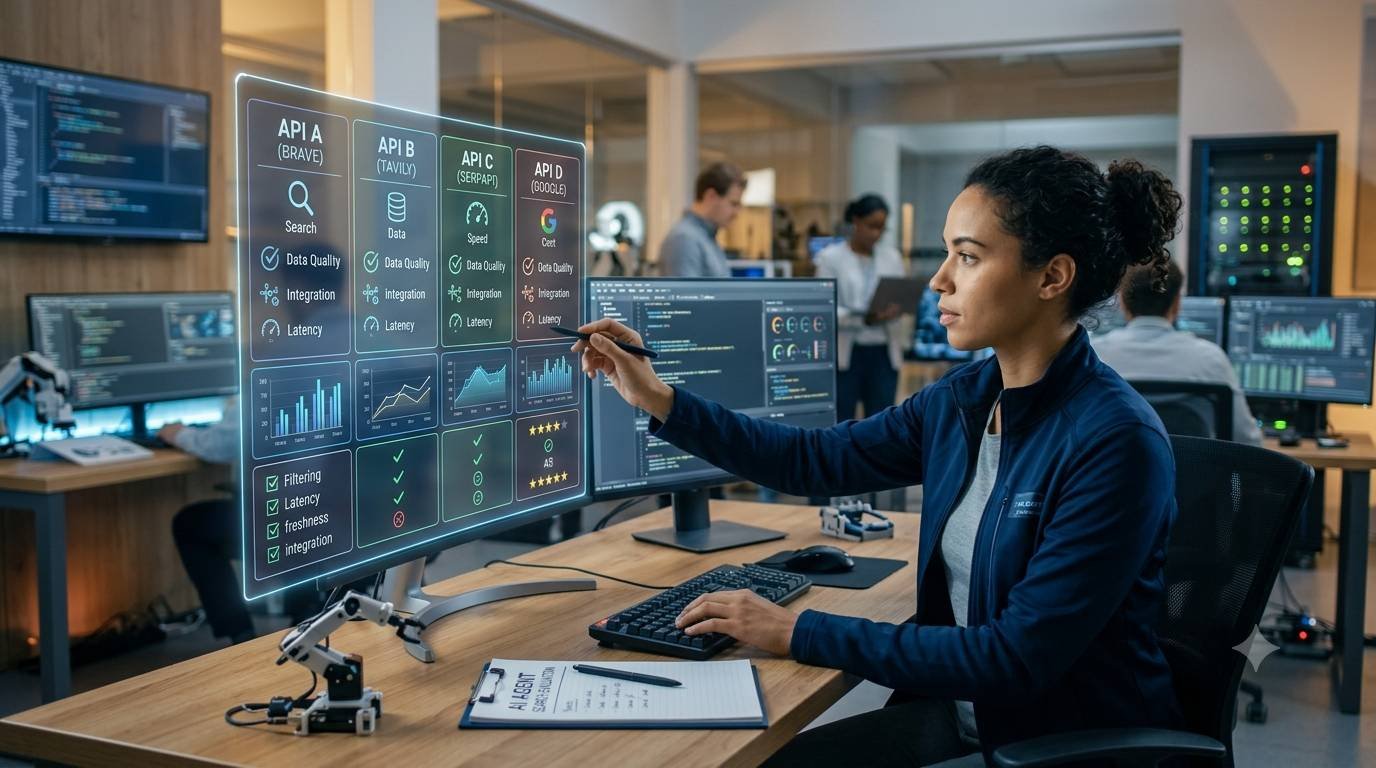
AI agents depend on search when they need current facts, supporting evidence, technical documentation, or pages that fall outside their built-in knowledge. Choosing the right provider is not simply a matter of comparing result counts or advertised response times. A comparison such as Exa versus Brave can be a useful starting point, but the final decision should reflect the work an agent must actually complete.
The strongest search API for one workflow may be a poor fit for another. A support agent may prioritize quick, concise results, while a research agent may need deeper coverage, reliable source metadata, and enough page context to produce a well-supported answer.
Why Search API Choice Matters
Search quality directly affects whether an agent can complete a task accurately and efficiently. Weak retrieval can lead a capable model to stale pages, duplicate content, irrelevant sources, or unsupported claims. Evaluate the API by completed task outcomes, not by the number of links returned. Accuracy, freshness, coverage, latency, cost, and integration effort all matter.
Start With the Agent’s Main Task
Define the job before comparing vendors. Customer-service agents may need trusted help center pages. Company research agents may need broad web coverage. News monitoring requires fresh results, while technical agents may need precise documentation. Write down required inputs, output format, acceptable response time, source restrictions, and whether every important claim needs a link.
Core Evaluation Metrics
A repeatable scorecard keeps comparisons focused. The core concepts of information retrieval provide a useful vocabulary for judging search quality.
- Relevance: Results match the request and its intent.
- Precision: A high share of returned results is genuinely useful.
- Recall: Important sources are not missed.
- Freshness: Recent or changing information appears when needed.
- Latency: Results arrive quickly enough for the workflow.
- Completeness: Responses contain needed fields, such as URLs, titles, dates, and excerpts.
- Reliability: Requests consistently return usable data.
- Effective cost: Total cost is measured per completed task.
Build a Fair Test Set
Give each candidate the same queries, filters, and result limits. Include easy, moderate, and difficult examples drawn from real agent traffic. Test recent events, rare names, technical terms, ambiguous wording, multiple conditions, and multi-step research. Add expected empty-result queries and error cases, since production systems must handle uncertainty as well as successful searches. Keep some questions held out until final scoring.
Use a simple review process. For each returned result, label it directly useful, partly useful, off-topic, duplicate, outdated, or untrustworthy. Review search quality separately from the final model response, because a polished answer can still rest on weak evidence. Track whether the agent answered from the returned material or had to perform more searches. Include multi-hop tasks that require comparing several pages before reaching a conclusion.
Check Speed and Reliability
Average latency can hide frustratingly slow requests. Record median latency along with 90th- and 99th-percentile response times. Test individual searches and longer chains where the agent makes repeated calls. Also record timeouts, retry outcomes, rate-limit behavior, partial responses, and malformed results. Small delays can compound when an agent performs several search, extraction, and verification steps for a single user request.
Review Cost and Scale
Estimate the cost of a full workflow, not one search call. Include result count, page extraction, reranking, retries, follow-up searches, and any model tokens created by lengthy excerpts. Build separate estimates for a small pilot, expected monthly use, and high-volume traffic. A lower listed request price may still result in higher operational costs if the agent needs more calls to find usable evidence.
Test Source Handling and Citations
Useful search output should include a stable URL, a readable title, the domain, publication date when available, and enough relevant text for the agent to judge the page. Test whether claims can be connected to the correct sources. Watch for copied content, broken links, duplicate pages, and summaries that omit essential context. A shorter set of credible, well-described sources is often more valuable than a long list of uncertain links.
Consider Security and Control
Retrieved web content is untrusted input. Pages may contain misleading instructions intended to influence an agent, so system instructions and tool permissions should remain separate from search results. Use domain controls to limit workflows to approved sources, and review logging, retention, access permissions, and regional requirements. The risk management practices for AI systems are a useful reminder to test for harmful or unexpected behavior before allowing agents to take consequential actions.
Run a Small Production Pilot
- Select a limited set of real tasks.
- Run each task through two or more candidates.
- Measure task success, speed, failures, source quality, and total cost.
- Ask users whether the output helped them complete work.
- Document missing data and unexpected behavior.
- Set pass and fail thresholds before reviewing results.
- Repeat the pilot after changing prompts, models, or API settings.
Common Questions
What Is the Most Important Search API Metric?
Task success is usually the best top-level metric. Relevance, freshness, latency, and cost explain why one provider succeeds more often than another.
Should Teams Prefer a Fast API or a More Accurate API?
It depends on the workflow. Live support may favor speed, while a research workflow may accept additional latency for stronger coverage and source depth.
How Often Should Search APIs Be Re-tested?
Re-test after major provider, pricing, model, prompt, or user-behavior changes. High-risk workflows benefit from ongoing monitoring of task outcomes and failures.
Final Takeaway
The best search API is the one that consistently helps an agent complete its intended work within acceptable limits on quality, speed, risk, and cost. A fair benchmark, careful source review, realistic cost model, and controlled production pilot turn a vague vendor comparison into a practical technical decision.